Showing posts with label ResearchFish. Show all posts

Sunday, 4 March 2018

How not to design the user experience: update 2018

In November 2014, I wrote a summary of my experience of entering research data in Researchfish. Since then, aspects of this system have improved: at least some of the most obvious bugs have been ironed out, and being able to link data from ORCID makes one tedious aspect of the task (entering data about particular publications) significantly easier. So well done to the ResearchFish team on fixing those problems. It's a pity it's still not fit for purpose, despite the number of funders who are supporting (mandating) use of this system.

The system is still designed without any consideration of how people conceptualise their research outputs – or at least, not how I do. According to ResearchFish, it takes less than a lunchbreak to enter all the data. There are two problems with this:
1. Few academics that I know have the time to take a lunch break.
2. So far, today, it has taken me longer than that just to work out a strategy for completing this multi-dimensional task systematically. It's like 3-D Sudoku, but less fun.

Even for publications, it's a two-dimensional task: select publications (e.g., from ORCID) and select grants to which they apply. But if you just do this as stated, then you get many-to-many relationships, with every publication assigned to grants that it isn't associated with as well as one(s) it is. And yes, I have tested this. So you have to decide which grant you're going to focus on, then go through the list and add those... then go around the loop (add new publications > select ORCID > search > select publications > select grant) repeatedly for all grants. Maybe there's a faster way to do it, but I haven't discovered that yet. Oh: and if you make a mistake, there isn't an easy way to correct it, so there is probably over-reporting as well as under-reporting on many grants.
I'm still trying to guess what "author not available" means in the information about a publication. My strategy for working out which paper each line refers to has been to keep Google Scholar open in parallel and search for the titles there, because those make more sense to me.

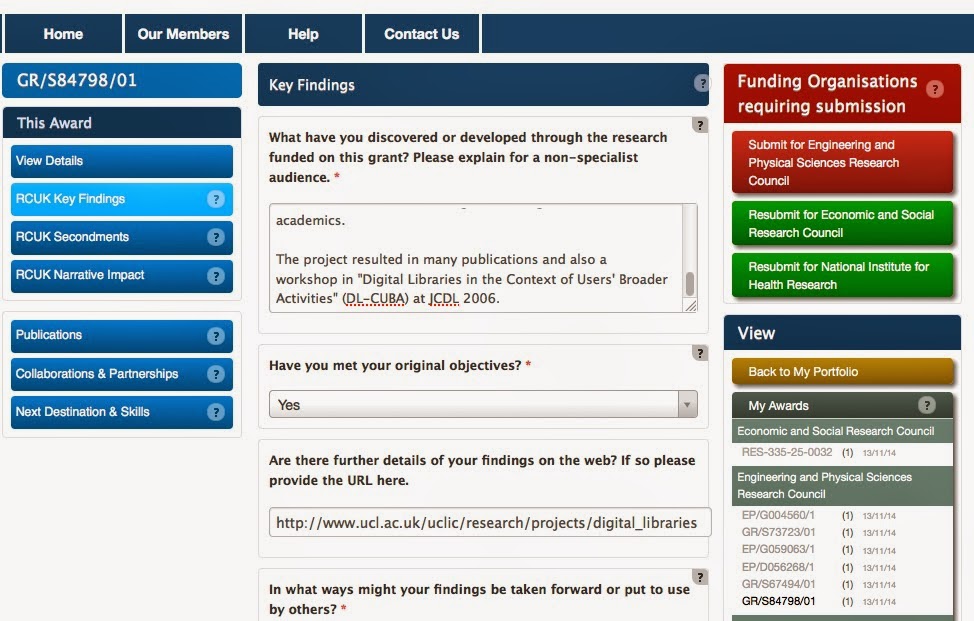
In the section on reporting key findings of a grant, when you save the entry, it returns you to the same page. Why would you want to save multiple times, rather than just moving on to the next step? Why isn't there a 'next' option? And why, when you have said there is no update on a completed grant, does it still take you to the update page? What was the point of the question?

When you're within the context of one award, and you select publications, it shows all publications for all awards (until you explicit select the option to focus on this award). Why? I'm in a particular task context...

When you're in the context of an award where you are simply a team member, you can filter by publications you've added, or by publications linked to this award, but not by publications that you've added that are also linked to this award. Those are the ones that I know about, and the ones that I want to check / update.

Having taken a coffee break, I returned to the interface to discover I had been logged out. I don't actually know my login details because the first time I logged in this morning I did so via ORCID. That option isn't available on the login page that appears after time-out. This is further evidence of poor system testing and non-existent user testing.

I could go on, but life is too short. There is no evidence of the developers having considered either conceptual design or task structures. There is no evidence that the system has actually been tested by real users who have real data entry tasks and time constraints. I really cannot comprehend how so many funders can mandate the use of a system that is so poorly designed, other than because they have the power to do so.

Wednesday, 5 November 2014

How not to design the user experience


Thank you to ResearchFish, a system that many UK researchers are required to use to report their research outcomes, for providing a rich set of examples of user experience bloopers. Enjoy! Or commiserate...

* The ‘opening the box’ experience: forget any idea that people have goals when using the system (in my case, to enter information about publications and other achievements based on recent grants held): just present people with an array of options, most of them irrelevant. If possible, hide the relevant options behind obscure labels, in the middle of several irrelevant options. Ensure that there is no clear semantic groupings of items. The more chaotic and confused the interaction, the more of an adventure it’ll be for the user.

* The conceptual model: introduce neat ideas that have the user guessing: what’s the difference between a team member and a delegate? What exactly is a portfolio, and what does it consist of? Users love guesswork when they’re trying to get a job done.

* Leave some things in an uncertain state. In the case of ResearchFish, some data had been migrated from a previous system. For this data, paper titles seem to have been truncated and many entries only have one page number. For example. Data quality is merely something to aspire to.

* Leave in a few basic bugs. For example, there was a point when I was allegedly looking at page 6 of 8, but there was only a ‘navigate back’ button: how would I look at page 7 of 8? [I don’t believe page 7 existed, but why did it claim that there were 8 pages?]

* If ‘slow food’ is good, then surely ‘slow computing’ must be too: every page refresh takes 6-8 seconds. Imagine that you are wading through treacle.

* Make it impossible to edit some data items. Even better: make it apparently a random subset of all possible data items.

* Don’t present data in a way that makes it clear what’s in the system and what might be missing. That would make things far too routine. Give the system the apparent structure of a haystack: some superficial structure on the outside, but pretty random when you look closer.

* Thomas Green proposed a notion of ‘viscosity’ of a system: make something that is conceptually simple difficult to do in practice. One form of viscosity is ‘repetition viscosity’. Bulk uploads? No way! People will enjoy adding entries one by one. One option for adding a publication entry is by DOI. So the cycle of activity is: identify a paper to be added; go to some other system (e.g., crossref); find the intended paper there; copy the DOI; return to ResearchFish; paste the DOI. Repeat. Repeatedly.

* Of course, some people may prefer to add entries in a different way. So add lots of other (equally tedious) alternative ways of adding entries. Keep the user guessing as to which will be the fastest for any given data type.

* Make people repeat work that’s already been done elsewhere. All my publications are (fairly reliably) recorded in Google Scholar and in the UCL IRIS system. I resorted at one point to accessing crossref, which isn’t exactly easy to use itself. So I was using one unusable system in order to populate another unusable system when all the information could be easily accessed via various other systems.

* Use meaningless codes where names would be far too obvious. Every publication has to be assigned to a grant by number. I don’t remember the number of every grant I have ever held. So I had to open another window to EPSRC Grants on the Web (GOW) in order to find out which grant number corresponds to which grant (as I think about it). For a while, I was working from four windows in parallel: scholar, crossref, GOW and ResearchFish. Later, I printed out the GOW page so that I could annotate it by hand to keep track of what I had done and what remained to be done. See Exhibit A.

* Tax the user’s memory: I am apparently required to submit entries for grants going back to 2006. I’ve had to start up an old computer to even find the files from those projects. And yes, the files include final reports that were submitted at the time. But now I’m expected to remember it all.

* Behave as if the task is trivial. The submission period is 4 weeks. A reminder to submit was sent out after two weeks. As if filling in this data is trivial. I reckon I have at least 500 outputs of one kind or another. Let’s say 10 minutes per output (to find and enter all the data and wait for the system response). Plus another 30-60 minutes per grant for entering narrative data. Yay: two weeks of my life when I am expected to teach, do research, manage projects, etc. etc. too.  And that assumes that it’s easy to organize the work, which it is not. So add at least another week to that estimate.

* Offer irrelevant error messages: At one point, I tried doing a Scopus search to find my own publications to enter them. Awful! When I tried selecting one and adding it to my portfolio, the response was "You are not authorized to access this page.” Oh: that was because I had a break between doing the search and selecting the entry, so my access had timed out. Why didn’t it say that?!? 

* Prioritise an inappropriate notion of security over usability: the security risk of leaving the page unattended was infinitesimal, while the frustration of time-out and lost data is significant, and yet researchfish timed out in the time it took to get a cup of coffee. I suspect the clock on the researchfish page may have been running all the time I was using the Scopus tool, but I'm not sure about that, and if I'm right then that's a crazy, crazy was to design the system. This kind of timeout is a great way of annoying users.

* Minimise organization of data: At one point, I had successfully found and added a few entries from Scopus, but also selected a lot of duplicate entries that are already in Researchfish. There is no way to tell which have already been added. And every time the user tries to tackle the challenge a different way it’s like starting again because every resource is organized differently. I have no idea how I would do a systematic check of completeness of reporting. This is what computers should be good at; it’s unwise to expect people to do it well.

* Sharing the task across a team? Another challenge. Everything is organised by principal investigator. You can add team members, but then who knows what everyone else is doing? If three co-authors are all able to enter data, they may all try. Only one will succeed, but why waste one person’s time when you can waste that of three (or more) people?

* Hide the most likely option. There are several drop-down menus where the default answer would be Great Britain / UK, but menu items are alphabetically ordered, so you have to scroll down to state the basically-obvious. And don’t over-shoot, or you have to scroll back up again. What a waste of time! There are other menus where the possible dates start at 1940: for reporting about projects going back to 2006. That means scrolling through over 60 years to find the most probable response.

* Assume user knowledge and avoid using forcing functions: at one point, I believed that I had submitted data for one funding body; the screen icon changed from “submit” to “resubmit” to reinforce this belief. But later someone told me there was a minimum data set that had to be submitted and I knew I had omitted some of that. So I went back and entered it. And hey presto: an email acknowledgement of submission. So I hadn’t actually submitted previously despite what the display showed. The system had let me apparently-submit without blocking that. But it wasn’t a real submission. And even now, I'm not sure that I have really submitted all the data since there is still an on-screen message telling me that it's still pending on the login page.

*Do not support multi-tasking. When I submitted data for one funding body, I wanted to get on with entering data for the next. But no: the system had to "process the submission" first. I cannot work while the computer system is working.

* Entice with inconsistency. See the order of the buttons for each of several grants (left). Every set is different. There are only 6 possible permutations of the three links under each grant heading; 5 of them are shown here. It must take a special effort to program the system to be so creative. Seriously: what does this inconsistency say about the software engineering of the system?
 
* Add enticing unpredictability. Spot the difference between the two screen shots on the right. And then take a guess at what I did to cause that change. It took me several attempts to work it out myself.

I started out trying to make this blog post light-hearted, maybe even amusing. But these problems are just scratching the surface of a system that is fundamentally unusable. Ultimately I find it really depressing that such systems are being developed and shipped in the 21st Century. What will it take to get the fundamentals of software engineering and user experience embedded in systems development?